NVIDIA CHALLENGE: OpenAI's Broadcom-Partnered Chip Aims at Data Center Dominance.
Gallery
Videos
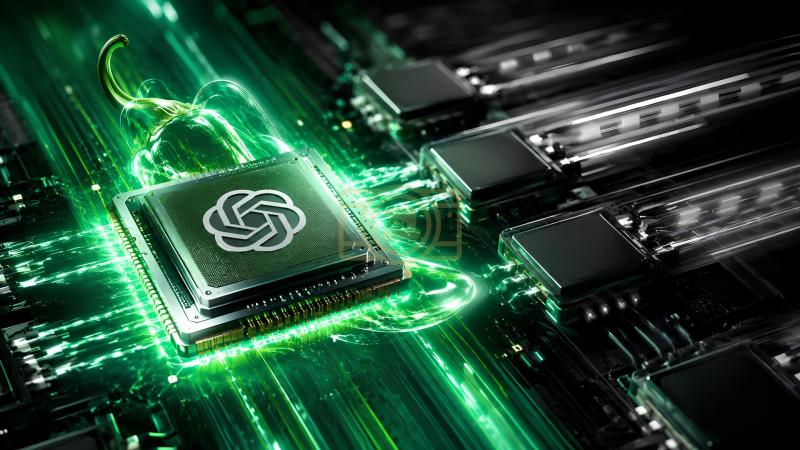
OpenAI has introduced its new Jalapeño chip with the claim that it could dramatically reduce the cost of running artificial intelligence systems. According to Richard Ho, the company’s vice president of hardware, the chip delivers between 1.8 times and 4 times better performance per watt than existing solutions. Those efficiency gains are expected to translate into lower token prices for customers once the chip reaches full production. The design focuses specifically on AI inference workloads rather than training. OpenAI positions the hardware as a key step toward making advanced AI more affordable at scale.
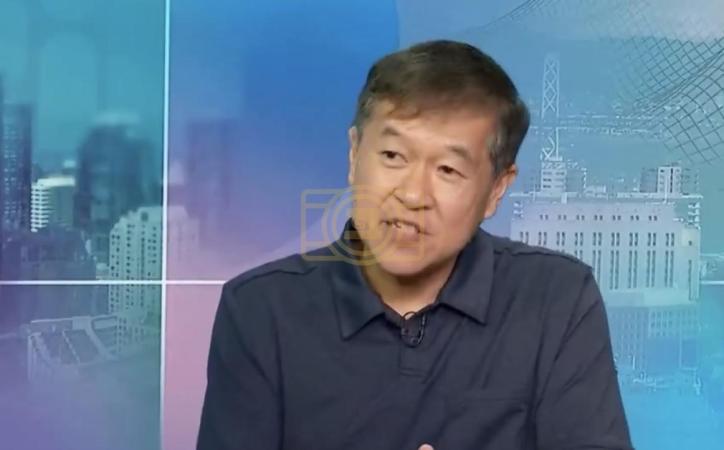
The Jalapeño chip forms part of a broader strategy to achieve end-to-end control over the AI technology stack. Ho explained in a Bloomberg TV segment that OpenAI is developing the custom silicon in partnership with Broadcom. This collaboration allows the company to optimize the hardware for its own models, including those powering ChatGPT and its API services. By tailoring the chip to specific workloads, OpenAI aims to extract greater efficiency than is possible with general-purpose processors. The approach reflects a growing desire among major AI developers to reduce dependence on external hardware suppliers.
Announced in June 2026, the chip arrives at a moment when data center power consumption has become a pressing industry concern. Rising electricity demands have increased the operational costs of large AI systems and intensified competition for more efficient designs. OpenAI’s performance-per-watt claims directly address that pressure. If the projected improvements hold in real-world deployment, the company could offer inference services at lower prices while managing energy use more effectively. The potential cost reduction is presented as a direct benefit for both OpenAI and its customers.
The move also places OpenAI in clearer competition with Nvidia, the current leader in AI accelerator hardware. By developing its own inference-focused chip, OpenAI seeks to capture a larger share of the value created by its models. Custom silicon optimized for ChatGPT and API traffic could give the company advantages in speed, power consumption, and ultimately pricing. Ho’s comments underscore that the hardware is intended to support the same services users already rely on, only more efficiently. Success will depend on how quickly the chip can be manufactured and integrated into existing data centers.
Efficiency improvements of the magnitude described would mark a meaningful shift in the economics of AI deployment. Token pricing has become a central factor for businesses and developers who use large language models at scale. Any sustained reduction in cost per token could expand access and encourage heavier usage. OpenAI’s decision to invest in specialized hardware signals confidence that vertical integration will deliver competitive advantages. The partnership with Broadcom provides the manufacturing expertise needed to turn the design into a production reality.
As the Jalapeño chip moves toward wider availability, attention will turn to independent verification of its performance claims and the actual impact on customer pricing. OpenAI has framed the project as a practical response to the twin challenges of rising power costs and the need for affordable inference. By controlling more of the stack, the company hopes to optimize every layer from model to silicon. The coming production phase will determine whether the promised efficiency gains materialize at commercial scale and how significantly they alter the cost structure of AI services.